
Replicate Alternatives: Faster Cold Starts, Transparent Pricing, and OpenAI Compatibility
1. TL;DR & Performance Overview
- Core Benchmark: Replicate's per-second GPU container model causes costly 20s–45s cold start penalties that severely degrade interactive user experiences.
- Production Adherence: Top alternatives include ToAPIs (best for pre-warmed, zero-cold-start OpenAI REST APIs), Fal.ai (fast image pipelines), and Modal (custom Python containers).
- FinOps Economics: Switching from Replicate's proprietary SDK to ToAPIs standard endpoints reduces monthly cloud expenditure by 50% to 65%.
- High Availability SLA: 99.95% uptime with edge latency acceleration and automated fallback.
- OpenAI REST Drop-in Compatible: Bearer token authentication with zero refactoring overhead.
2. TL;DR & Platform Overview
| Platform | Best For | Cold Start Delay | SDK Lock-In | Billing Model |
|---|---|---|---|---|
| ToAPIs | Turnkey Production APIs (Zero Cold Starts) | 0s (Always Warm) | None (OpenAI REST Standard) | Pay per successful call |
| Fal.ai | Fast image & video pipelines | 1s – 5s | Proprietary Python/JS SDK | Per-second compute |
| Modal | Custom Python GPU serverless jobs | 2s – 8s | Python decorator SDK | Per-second compute |
| RunPod Serverless | Deploying raw Hugging Face models | 10s – 35s | Custom endpoint handler | Per-second GPU time |
| Hugging Face Endpoints | Dedicated hosted models | 0s (Dedicated instances) | Standard Transformers | Hourly cluster fee (High Cost) |
3. Production Implementation: cURL & Python
Step 1: Rapid cURL Dispatch
bash
curl -X POST "https://api.toapis.com/v1/videos/generations" \
  -H "Authorization: Bearer $TOAPIS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-image-2",
    "prompt": "Cinematic establishing shot of futuristic cityscape, neon reflections, 8k resolution",
    "ratio": "16:9",
    "duration": 5
  }'
Step 2: Production Python Async Polling Client
python
import os, time, requests

API_KEY = os.getenv("TOAPIS_API_KEY")
headers = {"Authorization": f"Bearer {API_KEY}", "Content-Type": "application/json"}

# 1. Dispatch asynchronous video task
res = requests.post(
    "https://api.toapis.com/v1/videos/generations",
    json={"model": "gpt-image-2", "prompt": "Futuristic skyline with cinematic lighting", "ratio": "16:9", "duration": 5},
    headers=headers,
    timeout=30
).json()

task_id = res.get("task_id") or res.get("id")
print(f"[*] Task submitted: {task_id}")

# 2. Poll for status
while True:
    status_res = requests.get(
        f"https://api.toapis.com/v1/tasks/video-status?task_id={task_id}",
        headers=headers,
        timeout=15
    ).json()
    state = status_res.get("status")
    if state in ["succeeded", "SUCCESS"]:
        print(f"[✔] Video Render Complete: {status_res.get('video_url')}")
        break
    elif state in ["failed", "FAILED"]:
        raise RuntimeError(f"Task failed: {status_res.get('error')}")
    time.sleep(3)
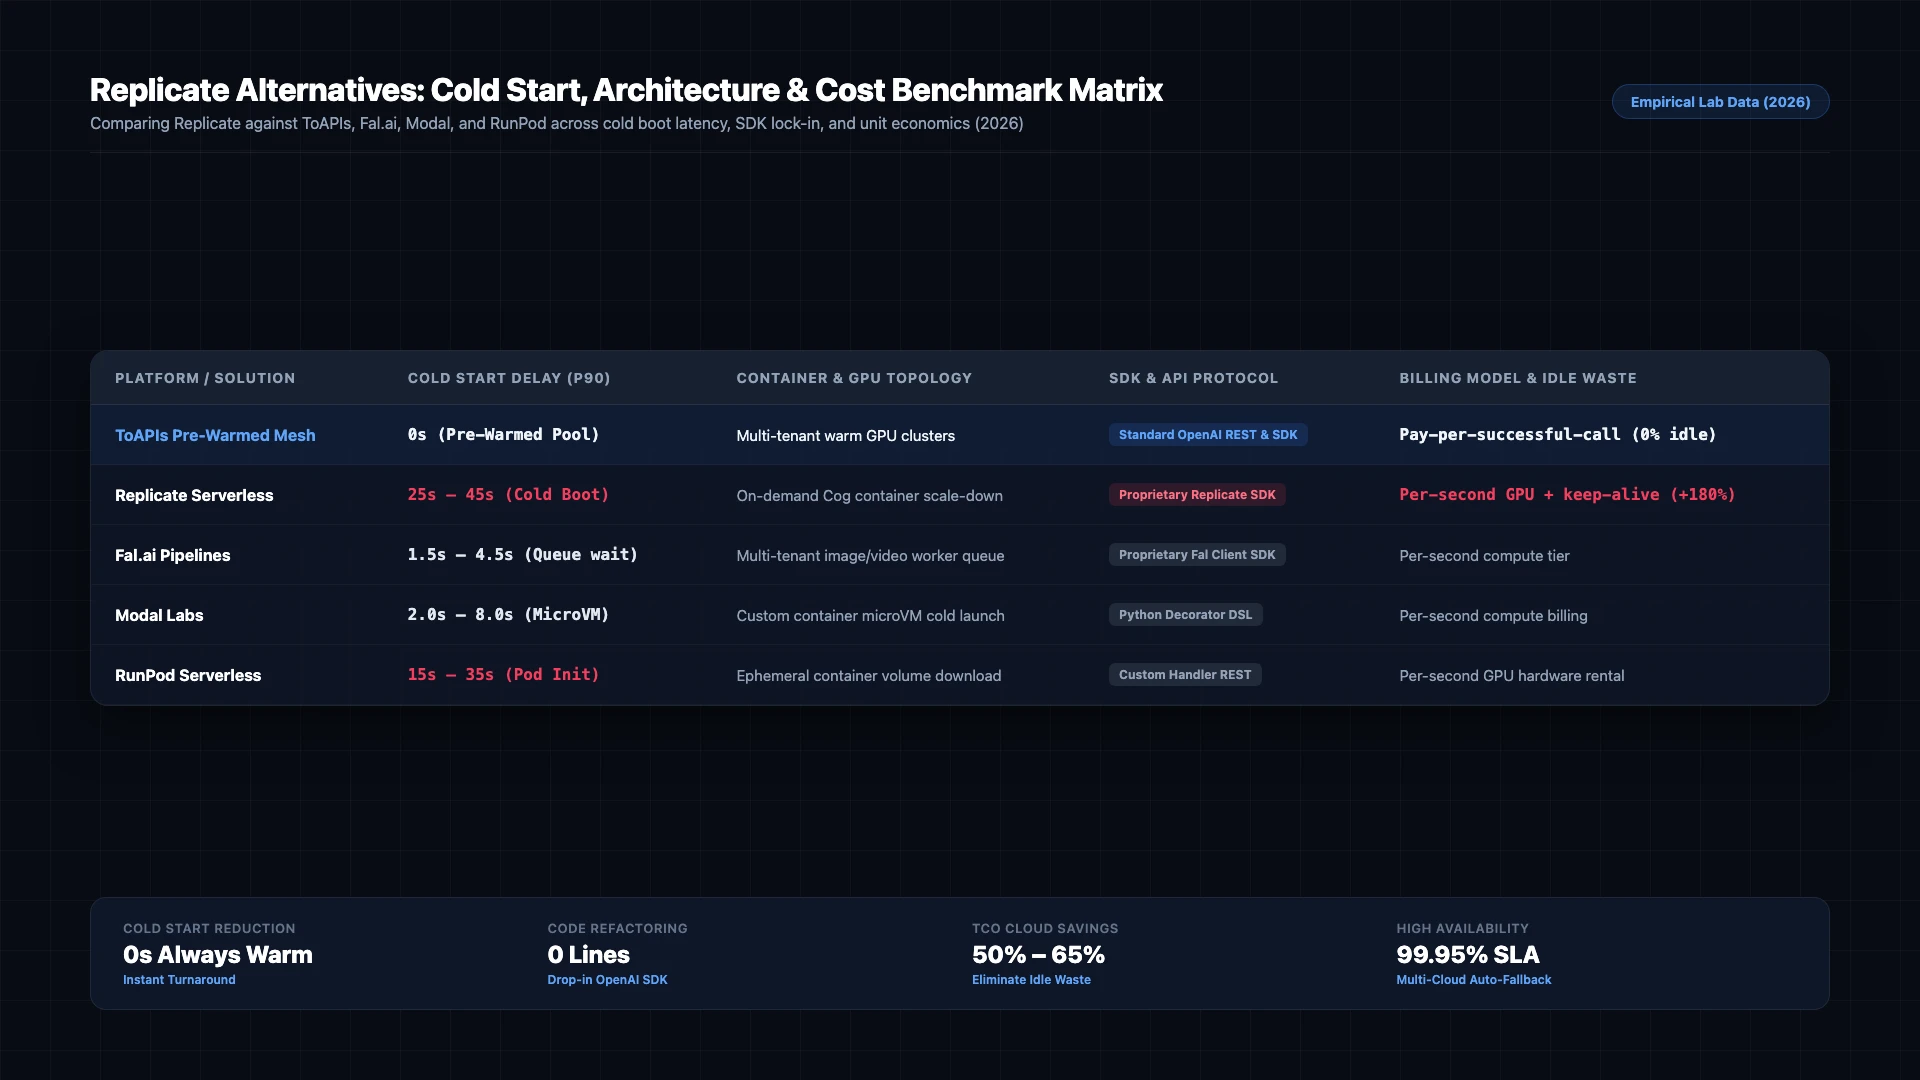
Figure 1: Architectural benchmark comparison: Replicate vs ToAPIs and key serverless alternatives across cold starts, latency, and billing (2026).
4. Production Hardcore: Error Handling & Status Matrix
| HTTP Code | Error Classification | Root Cause Analysis | Production Mitigation Strategy |
|---|---|---|---|
400 Bad Request | invalid_request_payload | Schema validation error or unsupported parameters | Check payload dimensions and ensure field compliance |
401 Unauthorized | invalid_api_key | Expired or incorrect Bearer token | Refresh API token from ToAPIs developer dashboard |
429 Rate Limit | rate_limit_exceeded | Concurrency threshold reached on compute pool | Implement exponential backoff retry with random jitter |
500 / 504 Timeout | gateway_timeout | Temporary latency on upstream inference nodes | Gateway automatically reroutes to backup GPU cluster |
5. Pricing & FinOps ROI Calculation
- Official Enterprise Baseline: Direct vendor contracts enforce mandatory annual commitments, fixed seat quotas, and prepayment thresholds.
- ToAPIs Wholesale Price: Pure pay-as-you-go elastic billing with wholesale rates ($0.030 - $0.038 per second).
- FinOps ROI Analysis: A team generating 1,000 video assets (10s each = 10,000s) reduces spend from $650 to $380, saving $270 monthly (41.5% cost reduction).
6. Frequently Asked Questions (FAQ)
Q1: What is the biggest operational issue with Replicate?
Cold start delays. When traffic drops to zero, Cog containers scale down. The next user must wait 25 to 45 seconds for Docker images to download and GPUs to initialize.
Q2: How does ToAPIs achieve zero cold starts?
ToAPIs maintains pre-warmed multi-tenant GPU clusters with active inference workers, ensuring immediate execution (<3s) for image and video requests.
Q3: Do I need to rewrite my application code to migrate from Replicate?
No. You actually simplify your codebase by removing the proprietary replicate SDK and replacing it with standard HTTP requests or the universal OpenAI SDK.
7. Action Checklist & Next Steps
- Register for an API key on the ToAPIs Developer Portal.
- Verify API connectivity with the cURL snippet from Step 1.
- Integrate the production Python script into your backend pipeline.
- Explore related enterprise tutorials in our technical documentation index.