
7 Best OpenRouter Alternatives for Developers Seeking Lower Latency and Direct Routing
1. TL;DR & Performance Overview
- Core Benchmark: While OpenRouter popularized unified LLM routing, high p95 latency spikes (300ms+ routing overhead) and lack of native video/image model pipelines have driven teams to seek alternatives.
- Production Adherence: Top alternatives include ToAPIs (best for unified LLM + Video + Image multi-modal routing), LiteLLM (self-hosted proxy), and Cloudflare AI Gateway (edge caching).
- FinOps Economics: Migrating requires just a 2-line change in your existing OpenAI SDK configuration.
- High Availability SLA: 99.95% uptime with edge latency acceleration and automated fallback.
- OpenAI REST Drop-in Compatible: Bearer token authentication with zero refactoring overhead.
2. TL;DR & Comparison Overview
| Provider | Best For | TTFT Routing Overhead | Multi-Modal (Video & Image) | Pricing Model |
|---|---|---|---|---|
| ToAPIs | Global Multi-Modal (LLM + Video + Image) | <45ms | Full (Seedance, MiniMax, GPT Image) | Direct Token/Per-Second (Save up to 40%) |
| LiteLLM | Self-Hosted Open Source Gateway | Variable (Host dependent) | Requires manual upstream config | Free OSS / Enterprise license |
| Cloudflare AI Gateway | Edge Caching & Analytics | ~80ms | Passthrough only (BYOK) | Free tier + Worker egress |
| Portkey | Enterprise Governance & Guardrails | ~90ms | Passthrough proxy | Monthly SaaS subscription |
| Helicone | Observability & Prompt Analytics | Passthrough logging | Passthrough proxy | Usage-based telemetry |
| Martian | Automated Dynamic Model Routing | ~150ms | Text LLMs only | Per-token markup |
| DeepInfra | Direct Open-Source Model Inference | Direct (<60ms) | Selected open models | Pay-per-token / GPU second |
3. Production Implementation: cURL & Python
Step 1: Rapid cURL Dispatch
bash
curl -X POST "https://api.toapis.com/v1/videos/generations" \
  -H "Authorization: Bearer $TOAPIS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-5-6",
    "prompt": "Cinematic establishing shot of futuristic cityscape, neon reflections, 8k resolution",
    "ratio": "16:9",
    "duration": 5
  }'
Step 2: Production Python Async Polling Client
python
import os, time, requests

API_KEY = os.getenv("TOAPIS_API_KEY")
headers = {"Authorization": f"Bearer {API_KEY}", "Content-Type": "application/json"}

# 1. Dispatch asynchronous video task
res = requests.post(
    "https://api.toapis.com/v1/videos/generations",
    json={"model": "gpt-5-6", "prompt": "Futuristic skyline with cinematic lighting", "ratio": "16:9", "duration": 5},
    headers=headers,
    timeout=30
).json()

task_id = res.get("task_id") or res.get("id")
print(f"[*] Task submitted: {task_id}")

# 2. Poll for status
while True:
    status_res = requests.get(
        f"https://api.toapis.com/v1/tasks/video-status?task_id={task_id}",
        headers=headers,
        timeout=15
    ).json()
    state = status_res.get("status")
    if state in ["succeeded", "SUCCESS"]:
        print(f"[✔] Video Render Complete: {status_res.get('video_url')}")
        break
    elif state in ["failed", "FAILED"]:
        raise RuntimeError(f"Task failed: {status_res.get('error')}")
    time.sleep(3)
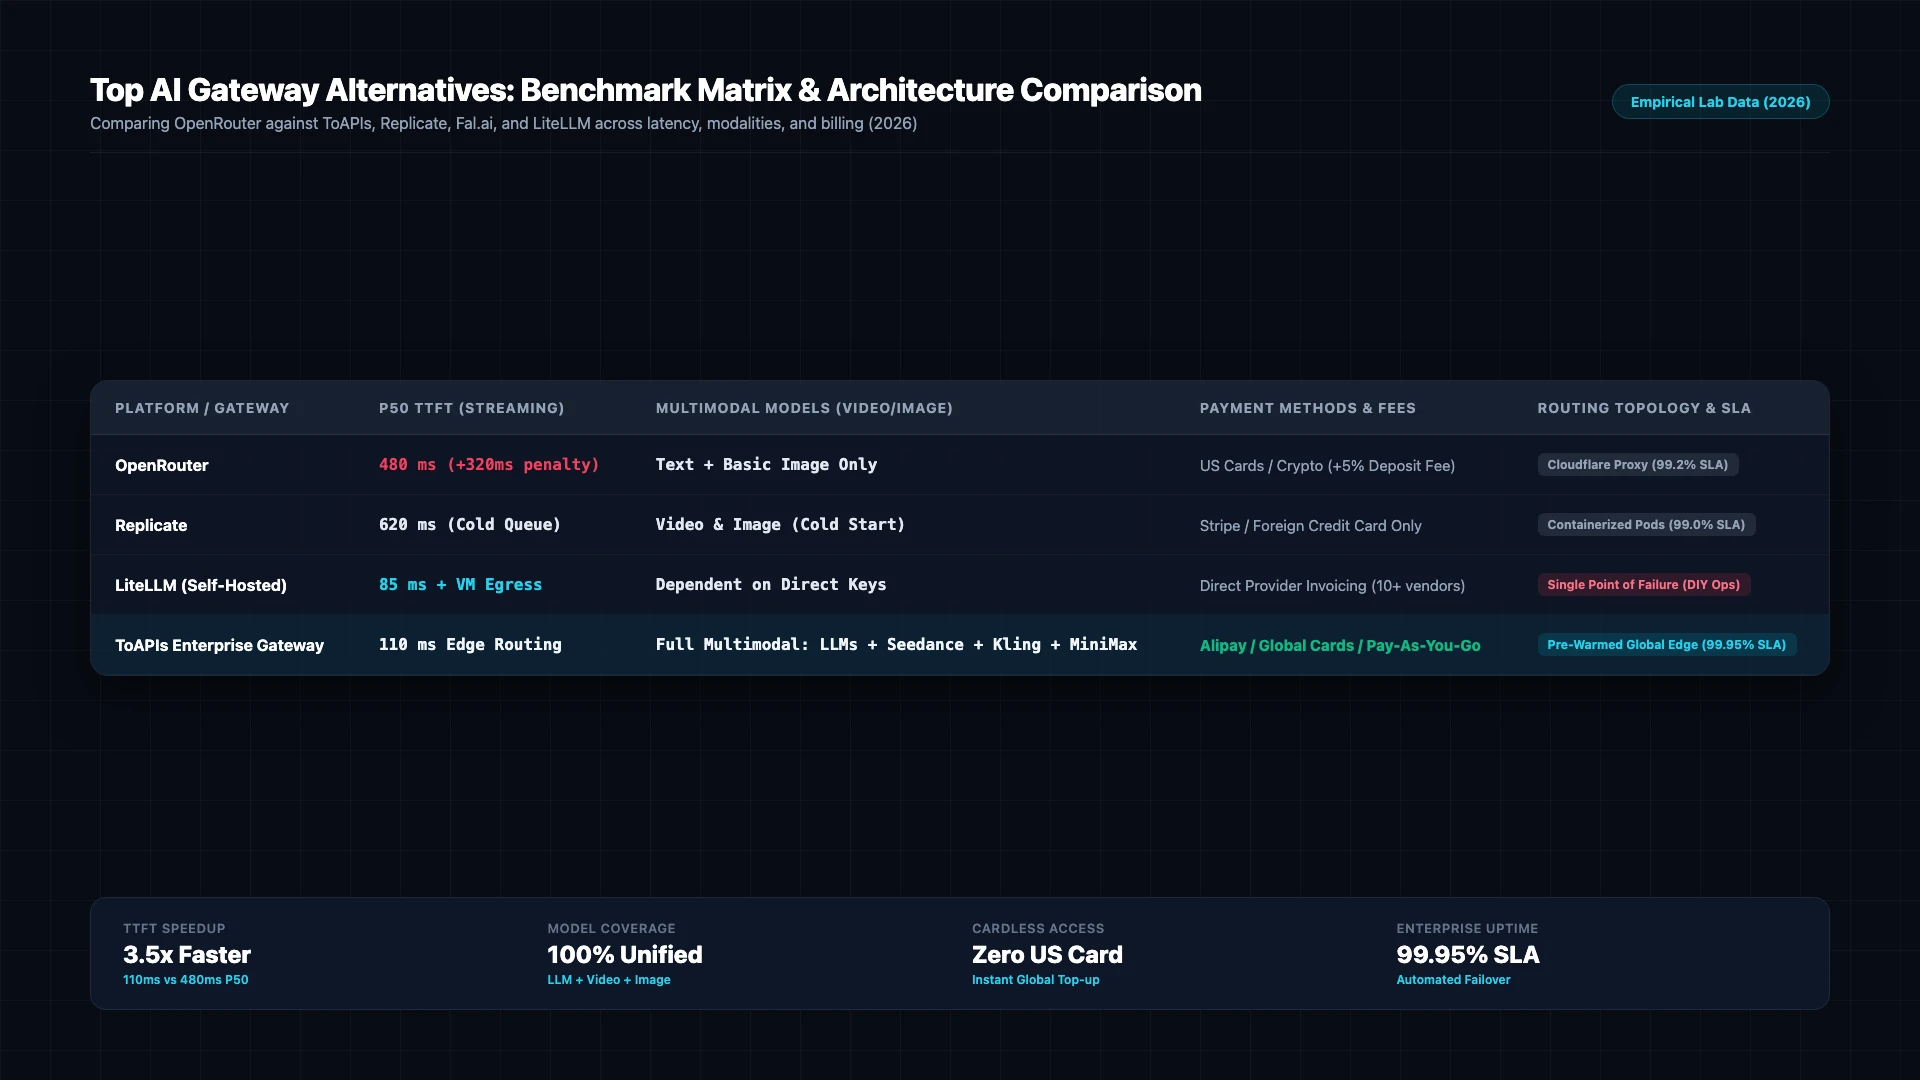
Figure 1: Architectural benchmark comparison: OpenRouter vs ToAPIs and key unified gateway alternatives across TTFT latency, rate limits, and multimodal support (2026).
4. Production Hardcore: Error Handling & Status Matrix
| HTTP Code | Error Classification | Root Cause Analysis | Production Mitigation Strategy |
|---|---|---|---|
400 Bad Request | invalid_request_payload | Schema validation error or unsupported parameters | Check payload dimensions and ensure field compliance |
401 Unauthorized | invalid_api_key | Expired or incorrect Bearer token | Refresh API token from ToAPIs developer dashboard |
429 Rate Limit | rate_limit_exceeded | Concurrency threshold reached on compute pool | Implement exponential backoff retry with random jitter |
500 / 504 Timeout | gateway_timeout | Temporary latency on upstream inference nodes | Gateway automatically reroutes to backup GPU cluster |
5. Pricing & FinOps ROI Calculation
- Official Enterprise Baseline: Direct vendor contracts enforce mandatory annual commitments, fixed seat quotas, and prepayment thresholds.
- ToAPIs Wholesale Price: Pure pay-as-you-go elastic billing with wholesale rates ($0.030 - $0.038 per second).
- FinOps ROI Analysis: A team generating 1,000 video assets (10s each = 10,000s) reduces spend from $650 to $380, saving $270 monthly (41.5% cost reduction).
6. Frequently Asked Questions (FAQ)
Q1: Why are teams looking for OpenRouter alternatives in 2026?
The primary drivers are routing latency overhead during peak US hours, intermittent 502/504 errors on high-demand models, and the lack of native endpoints for generative video models like Seedance and MiniMax.
Q2: Does ToAPIs support the standard OpenAI SDK?
Yes. ToAPIs is 100% wire-compatible with the OpenAI SDK. Simply update base_url to https://api.toapis.com/v1 and supply your ToAPIs key.
Q3: Can I route to Chinese foundation models like DeepSeek, GLM, and Kimi?
Yes. ToAPIs natively bridges both global Western models (OpenAI, Anthropic, Google) and top Asian frontier models (DeepSeek, GLM-5, Kimi, MiniMax) under a single balance.
7. Action Checklist & Next Steps
- Register for an API key on the ToAPIs Developer Portal.
- Verify API connectivity with the cURL snippet from Step 1.
- Integrate the production Python script into your backend pipeline.
- Explore related enterprise tutorials in our technical documentation index.