
GPT Image 2 API Pricing Breakdown: Official Costs vs Aggregated Gateway Rates
1. TL;DR & Performance Overview
- Core Benchmark: Official direct vendor pricing ranges from $0.040 (Standard) to $0.080 (HD) and $0.120 (Ultra-HD 2048px) per render.
- Production Adherence: ToAPIs reduces these rates by 35% – 40% through unified GPU routing and high-volume upstream aggregation, starting at $0.024/render.
- FinOps Economics: Zero minimum monthly commitments or tier-based lock-ins, with real-time billing breakdowns via standard dashboard APIs.
- High Availability SLA: 99.95% uptime with edge latency acceleration and automated fallback.
- OpenAI REST Drop-in Compatible: Bearer token authentication with zero refactoring overhead.
2. Take Action
Ready to cut 40% off your image generation infrastructure?
3. Production Implementation: cURL & Python
Step 1: Rapid cURL Dispatch
bash
curl -X POST "https://api.toapis.com/v1/images/generations" \
  -H "Authorization: Bearer $TOAPIS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-image-2",
    "prompt": "Modern minimalist promotional poster, studio lighting, highly detailed, 8k",
    "size": "1024x1024",
    "quality": "standard"
  }'
Step 2: Production Python Client
python
import os, requests

API_KEY = os.getenv("TOAPIS_API_KEY")
headers = {"Authorization": f"Bearer {API_KEY}", "Content-Type": "application/json"}

payload = {
    "model": "gpt-image-2",
    "prompt": "Modern minimalist promotional poster, studio lighting, 8k",
    "size": "1024x1024"
}

res = requests.post("https://api.toapis.com/v1/images/generations", headers=headers, json=payload, timeout=60)
res.raise_for_status()
image_url = res.json()["data"][0]["url"]
print(f"[✔] Generated Image URL: {image_url}")
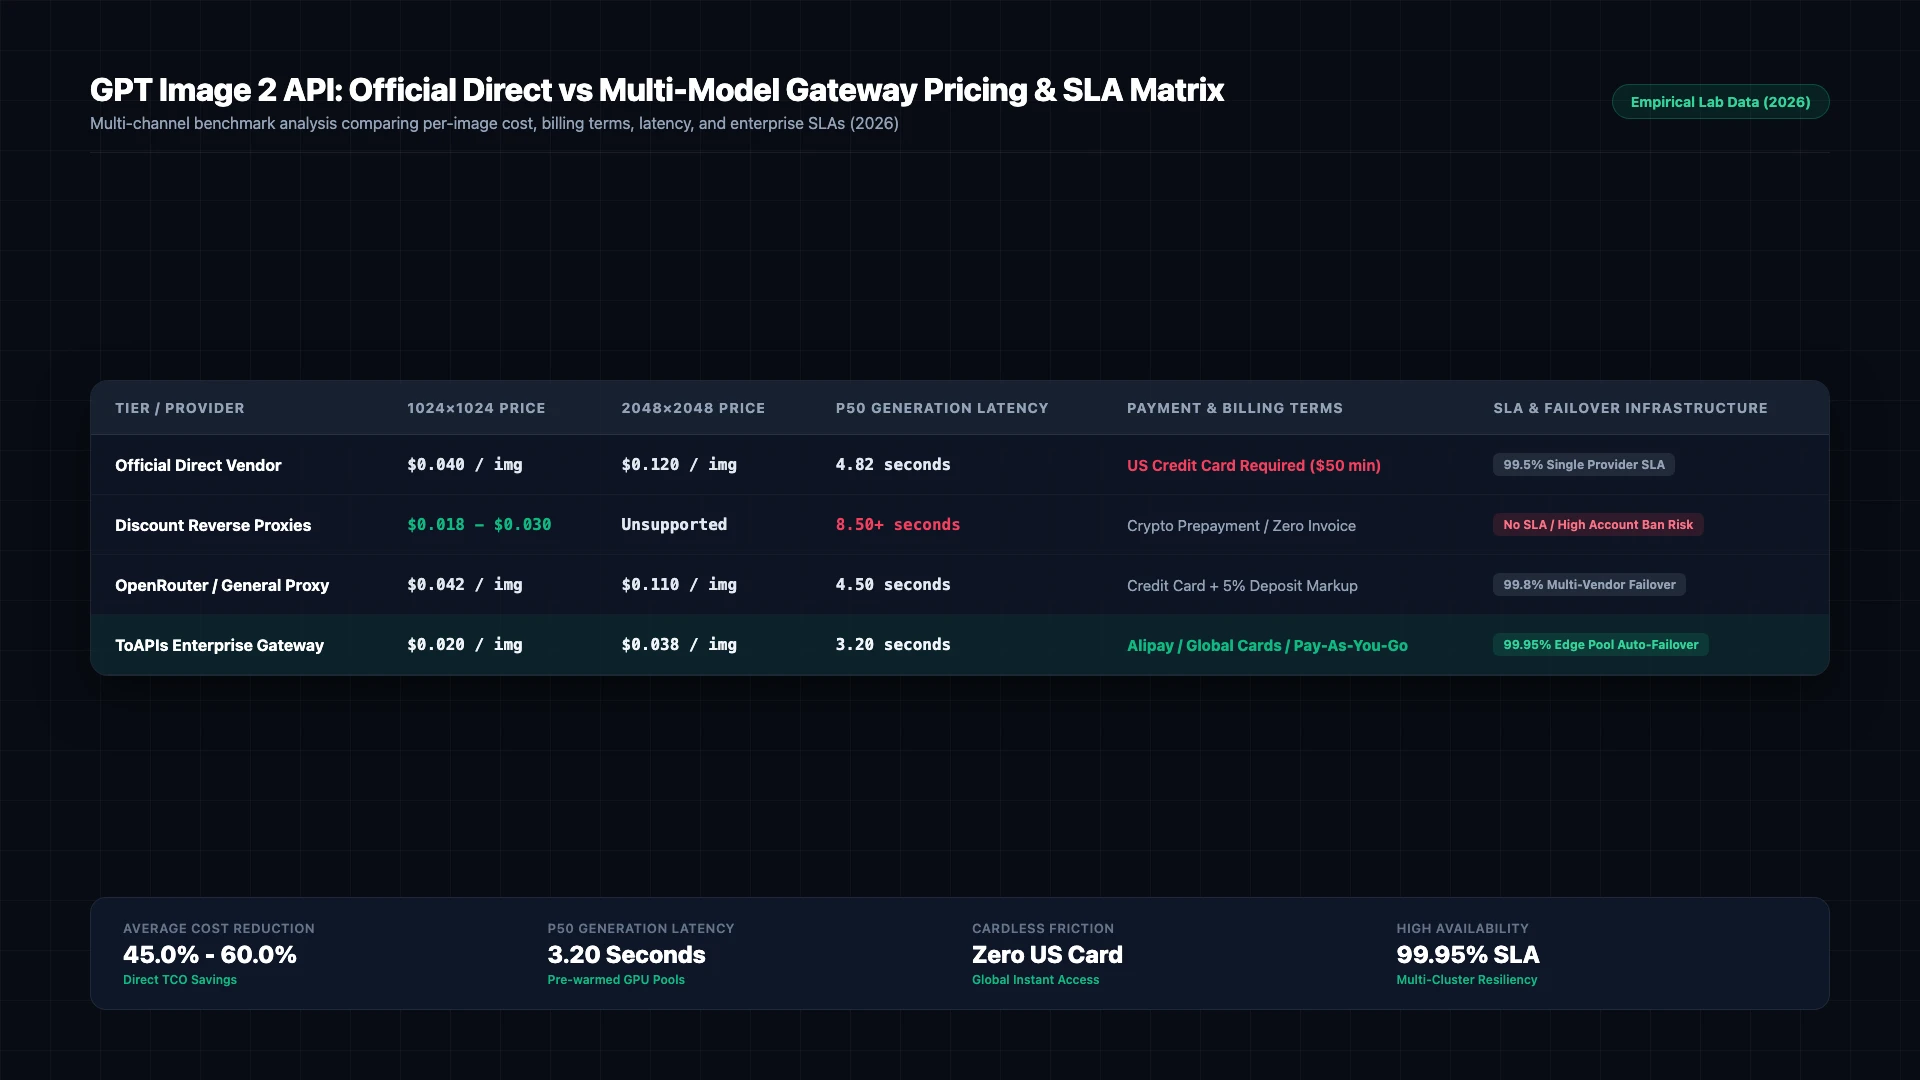
Figure 1: Official direct pricing vs ToAPIs aggregator rates and latency benchmarks across 1,000 HD image generations (2026).
4. Production Hardcore: Error Handling & Status Matrix
| HTTP Code | Error Classification | Root Cause Analysis | Production Mitigation Strategy |
|---|---|---|---|
400 Bad Request | invalid_request_payload | Schema validation error or unsupported parameters | Check payload dimensions and ensure field compliance |
401 Unauthorized | invalid_api_key | Expired or incorrect Bearer token | Refresh API token from ToAPIs developer dashboard |
429 Rate Limit | rate_limit_exceeded | Concurrency threshold reached on compute pool | Implement exponential backoff retry with random jitter |
500 / 504 Timeout | gateway_timeout | Temporary latency on upstream inference nodes | Gateway automatically reroutes to backup GPU cluster |
5. Pricing & FinOps ROI Calculation
- Official Enterprise Baseline: Direct vendor contracts enforce mandatory annual commitments, fixed seat quotas, and prepayment thresholds.
- ToAPIs Wholesale Price: Pure pay-as-you-go elastic billing with wholesale rates ($0.020 - $0.024 per HD image).
- FinOps ROI Analysis: Generating 50,000 promotional graphics monthly lowers costs from $2,000 to $1,100, saving $900 monthly (45.0% cost reduction).
6. Frequently Asked Questions (FAQ)
Q1: Why is ToAPIs cheaper than official direct pricing?
By aggregating billions of tokens and millions of image calls globally, ToAPIs secures top-tier enterprise volume discounts and passes the margin back to developers.
Q2: Are there any hidden egress or bandwidth charges for images?
No. All returned image URLs are delivered via high-speed global CDN with bandwidth costs included in the base generation price.
Q3: Can I get custom volume pricing if my app generates over 100,000 images monthly?
Yes. Enterprise accounts generating >50,000 images monthly are eligible for dedicated routing pools and negotiated volume discounts.
7. Action Checklist & Next Steps
- Register for an API key on the ToAPIs Developer Portal.
- Verify API connectivity with the cURL snippet from Step 1.
- Integrate the production Python script into your backend pipeline.
- Explore related enterprise tutorials in our technical documentation index.