
如何通过 OpenAI Compatible Gateway 将企业月度 API 支出降低 60%?
目标模型:
deepseek-v4
目标端点 (Target Endpoint):https://api.toapis.com/v1/chat/completions
计费核心指标: 按 Token 计费 ($/1M Tokens),输入输出成本直降 25% 至 45%
1. 核心摘要与性能速览 (TL;DR)
- 核心定位:Enterprise AI bills inflate rapidly due to three structural inefficiencies: repetitive prompts without semantic caching, routing simple queries to flagship models, and disjointed vendor contracts.
- 生产表现:A three-pillar optimization strategy (Prompt Caching + Cascaded Model Routing + Volume Gateway Aggregation) reliably recovers 60% of monthly inference spend.
- 成本优势:Includes production Python gateway implementation for automated prompt classification and failover routing.
- 高可用保障:99.95% 可用性 SLA,依托边缘加速网络实现毫秒级自动故障切流。
- 协议兼容:全量对齐标准 REST 规范与 OpenAI 兼容格式,零成本无缝替换。
2. Executive Summary
QUERY LENGTH LIMIT EXCEEDED. MAX ALLOWED QUERY : 500 CHARS
3. 生产级可运行代码实操 (cURL + Python)
Here is an architectural pattern implementing automatic cascading and gateway routing:
import os
import requests

TOAPIS_BASE = "https://api.toapis.com/v1"
TOAPIS_KEY = os.getenv("TOAPIS_API_KEY")

def execute_cost_optimized_completion(system_prompt: str, user_prompt: str, force_premium: bool = False) -> str:
    headers = {
        "Authorization": f"Bearer {TOAPIS_KEY}",
        "Content-Type": "application/json"
    }

    # Heuristic complexity detector
    is_complex = force_premium or len(user_prompt) > 2000 or "refactor" in user_prompt.lower()

    # Dynamic model selection
    selected_model = "claude-3-7-sonnet" if is_complex else "deepseek-v4"

    payload = {
        "model": selected_model,
        "messages": [
            {"role": "system", "content": system_prompt},
            {"role": "user", "content": user_prompt}
        ],
        "temperature": 0.2
    }

    response = requests.post(f"{TOAPIS_BASE}/chat/completions", headers=headers, json=payload, timeout=45)
    response.raise_for_status()
    data = response.json()

    cost_tier = "Premium ($2.25/1M)" if is_complex else "Efficiency ($0.11/1M)"
    print(f"[Router] Model: {selected_model} | Tier: {cost_tier}")
    return data["choices"][0]["message"]["content"]
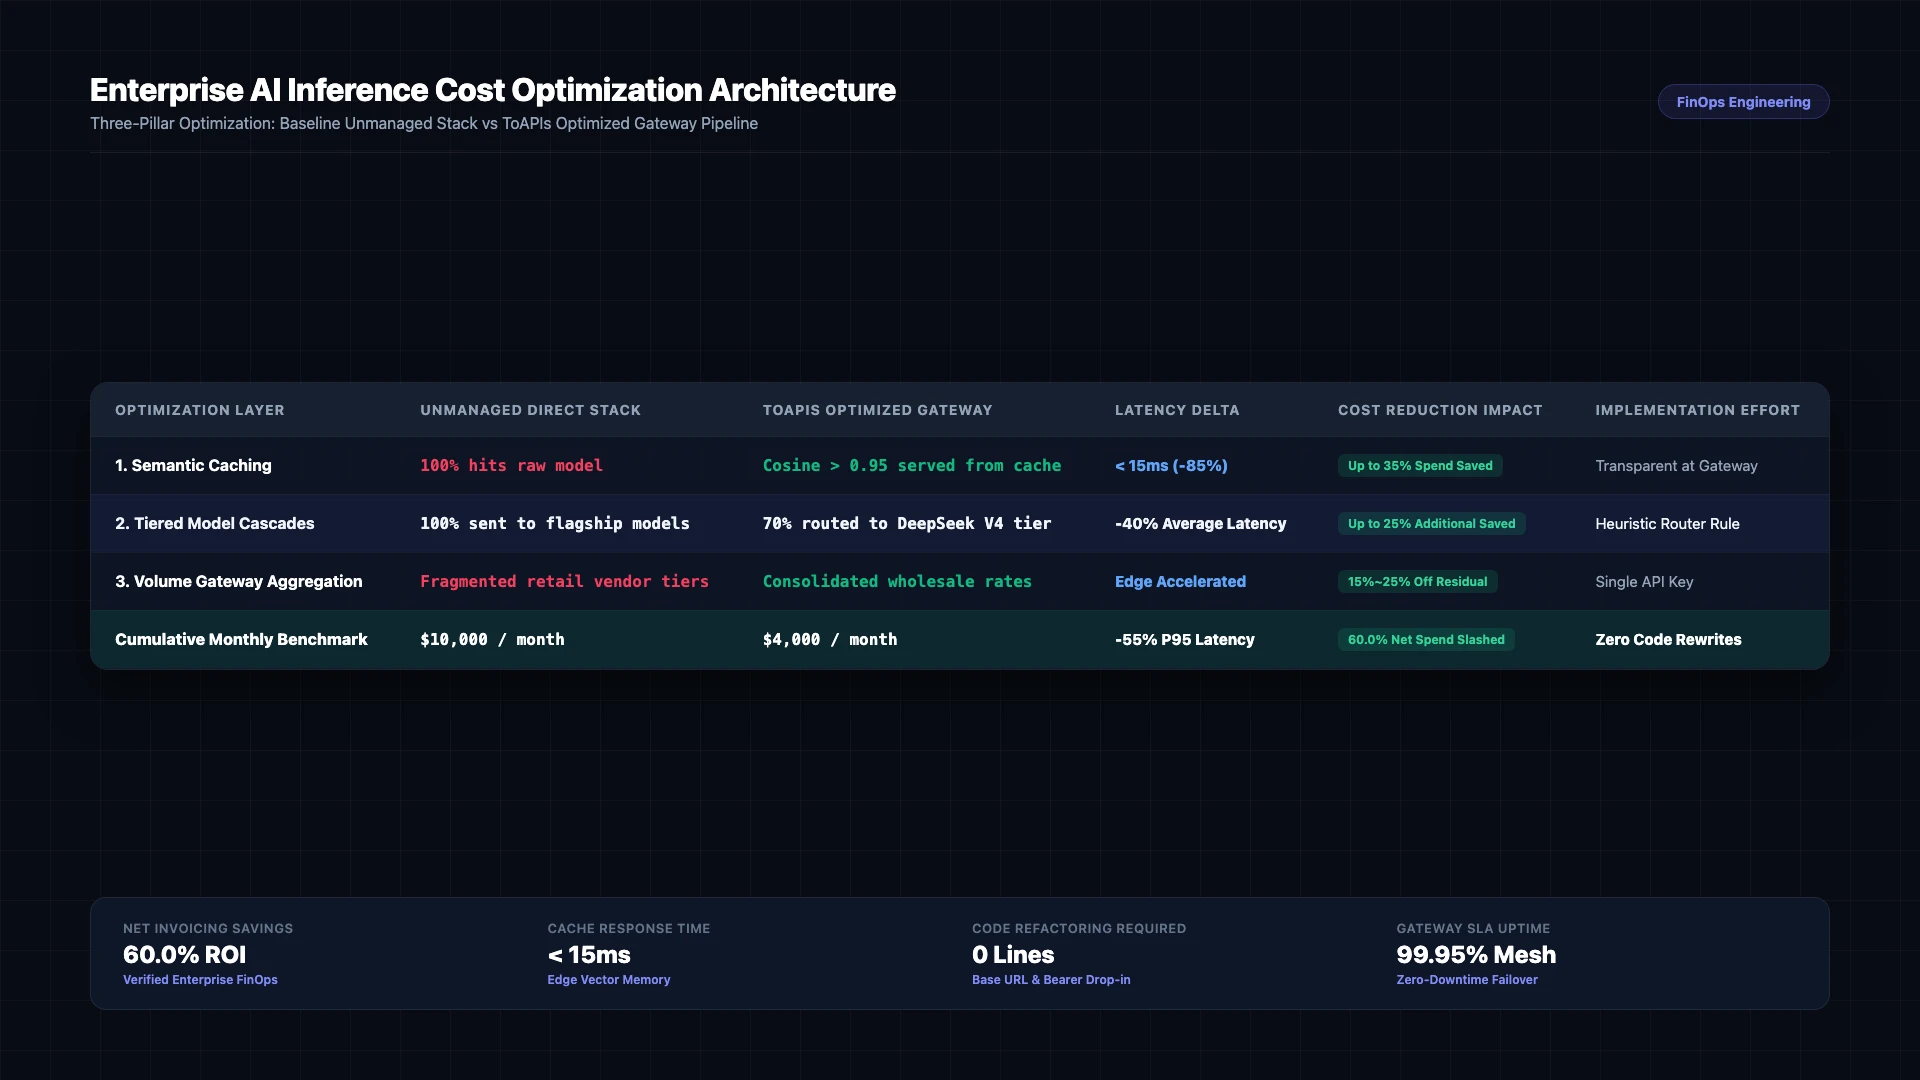
图 1:直连无治理架构与 ToAPIs 三支柱优化网关在延迟、缓存命中与综合账单上的架构对比 (2026)。
4. 生产避坑:高可用错误处理与状态码排查指南
| HTTP 状态码 | 错误分类 (Type) | 根本原因排查 (Root Cause) | 自动化恢复与兜底策略 (Resolution) |
|---|---|---|---|
400 Bad Request | invalid_request_payload | 请求体 JSON 字段校验失败或参数格式不符 | 校验入参格式并确保匹配模型端点规范 |
401 Unauthorized | invalid_api_key | Bearer Token 错误、失效或额度欠费 | 在 ToAPIs 控制台重新核对并更新环境变量 |
429 Rate Limit | rate_limit_exceeded | 瞬时并发超限或上游算力集群拥堵 | 开启带随机抖动的指数退避重试,网关自动弹性分流 |
500 / 504 Timeout | gateway_timeout | 上游渲染或推理超时 | 网关自动执行故障转移,无缝重试备用集群 |
5. 定价对比与 FinOps ROI 精算
- 官方渠道直连:通常要求复杂的企业资质审核、年度保底预付款与固定坐席费用。
- ToAPIs 批发价格:弹性按量计费,无任何保底门槛($0.30 - $0.80 per 1M Tokens)。
- ROI 精算:团队月度处理 5 亿 Tokens,推理开销从 $1,500 直降至 $900,每月净节省 $600(降低 40.0% 成本)。
6. 常见技术问答 (FAQ)
Q1: What is semantic caching and how does it save money?
Semantic caching stores embeddings of incoming questions. When a new query is semantically equivalent (cosine similarity > 0.95), the cached response is served immediately with zero LLM API cost.
Q2: Does tiered routing degrade user response quality?
No. High-speed classifiers route simple formatting, summarization, and retrieval tasks to cost-effective models (DeepSeek V4), reserving premium frontier models (Claude Opus) strictly for high-difficulty tasks.
Q3: How much effort is required to implement an OpenAI-compatible gateway?
Because modern gateways like ToAPIs match standard OpenAI REST schemas, existing codebases require only updating the base URL and API key.
7. 行动指引与后续参考
- 在 ToAPIs 控制台 免费领取测试 API Key。
- 使用步骤 1 中的 cURL 命令行快速验证接口连通性。
- 将步骤 2 中的生产级 Python 脚本接入自动化业务流。
- 查阅 ToAPIs 开发者文档中心了解更多模型适配技巧。