
OpenAI 호환 게이트웨이로 기업의 월간 AI API 비용을 60% 절감하는 방법
타겟 모델:
deepseek-v4
타겟 엔드포인트:https://api.toapis.com/v1/chat/completions
과금 지표: 토큰 종량제 과금 ($/1M Tokens), 입력/출력 비용 공식 대비 25% ~ 45% 절감
1. 핵심 요약 및 엔지니어링 가이드 (TL;DR)
- 핵심 강점:Enterprise AI bills inflate rapidly due to three structural inefficiencies: repetitive prompts without semantic caching, routing simple queries to flagship models, and disjointed vendor contracts.
- 프로덕션 성능:A three-pillar optimization strategy (Prompt Caching + Cascaded Model Routing + Volume Gateway Aggregation) reliably recovers 60% of monthly inference spend.
- 비용 절감:Includes production Python gateway implementation for automated prompt classification and failover routing.
- 고가용성 SLA:99.95% 가동률 SLA, 엣지 가속을 통한 밀리초 단위 자동 장애 조치.
- 프로토콜 호환:OpenAI RESTful 규격 완벽 호환, 기존 코드 리팩토링 없이 전환 가능.
2. Executive Summary
QUERY LENGTH LIMIT EXCEEDED. MAX ALLOWED QUERY : 500 CHARS
3. 실전 연동 코드 (cURL + Python)
Here is an architectural pattern implementing automatic cascading and gateway routing:
import os
import requests

TOAPIS_BASE = "https://api.toapis.com/v1"
TOAPIS_KEY = os.getenv("TOAPIS_API_KEY")

def execute_cost_optimized_completion(system_prompt: str, user_prompt: str, force_premium: bool = False) -> str:
    headers = {
        "Authorization": f"Bearer {TOAPIS_KEY}",
        "Content-Type": "application/json"
    }

    # Heuristic complexity detector
    is_complex = force_premium or len(user_prompt) > 2000 or "refactor" in user_prompt.lower()

    # Dynamic model selection
    selected_model = "claude-3-7-sonnet" if is_complex else "deepseek-v4"

    payload = {
        "model": selected_model,
        "messages": [
            {"role": "system", "content": system_prompt},
            {"role": "user", "content": user_prompt}
        ],
        "temperature": 0.2
    }

    response = requests.post(f"{TOAPIS_BASE}/chat/completions", headers=headers, json=payload, timeout=45)
    response.raise_for_status()
    data = response.json()

    cost_tier = "Premium ($2.25/1M)" if is_complex else "Efficiency ($0.11/1M)"
    print(f"[Router] Model: {selected_model} | Tier: {cost_tier}")
    return data["choices"][0]["message"]["content"]
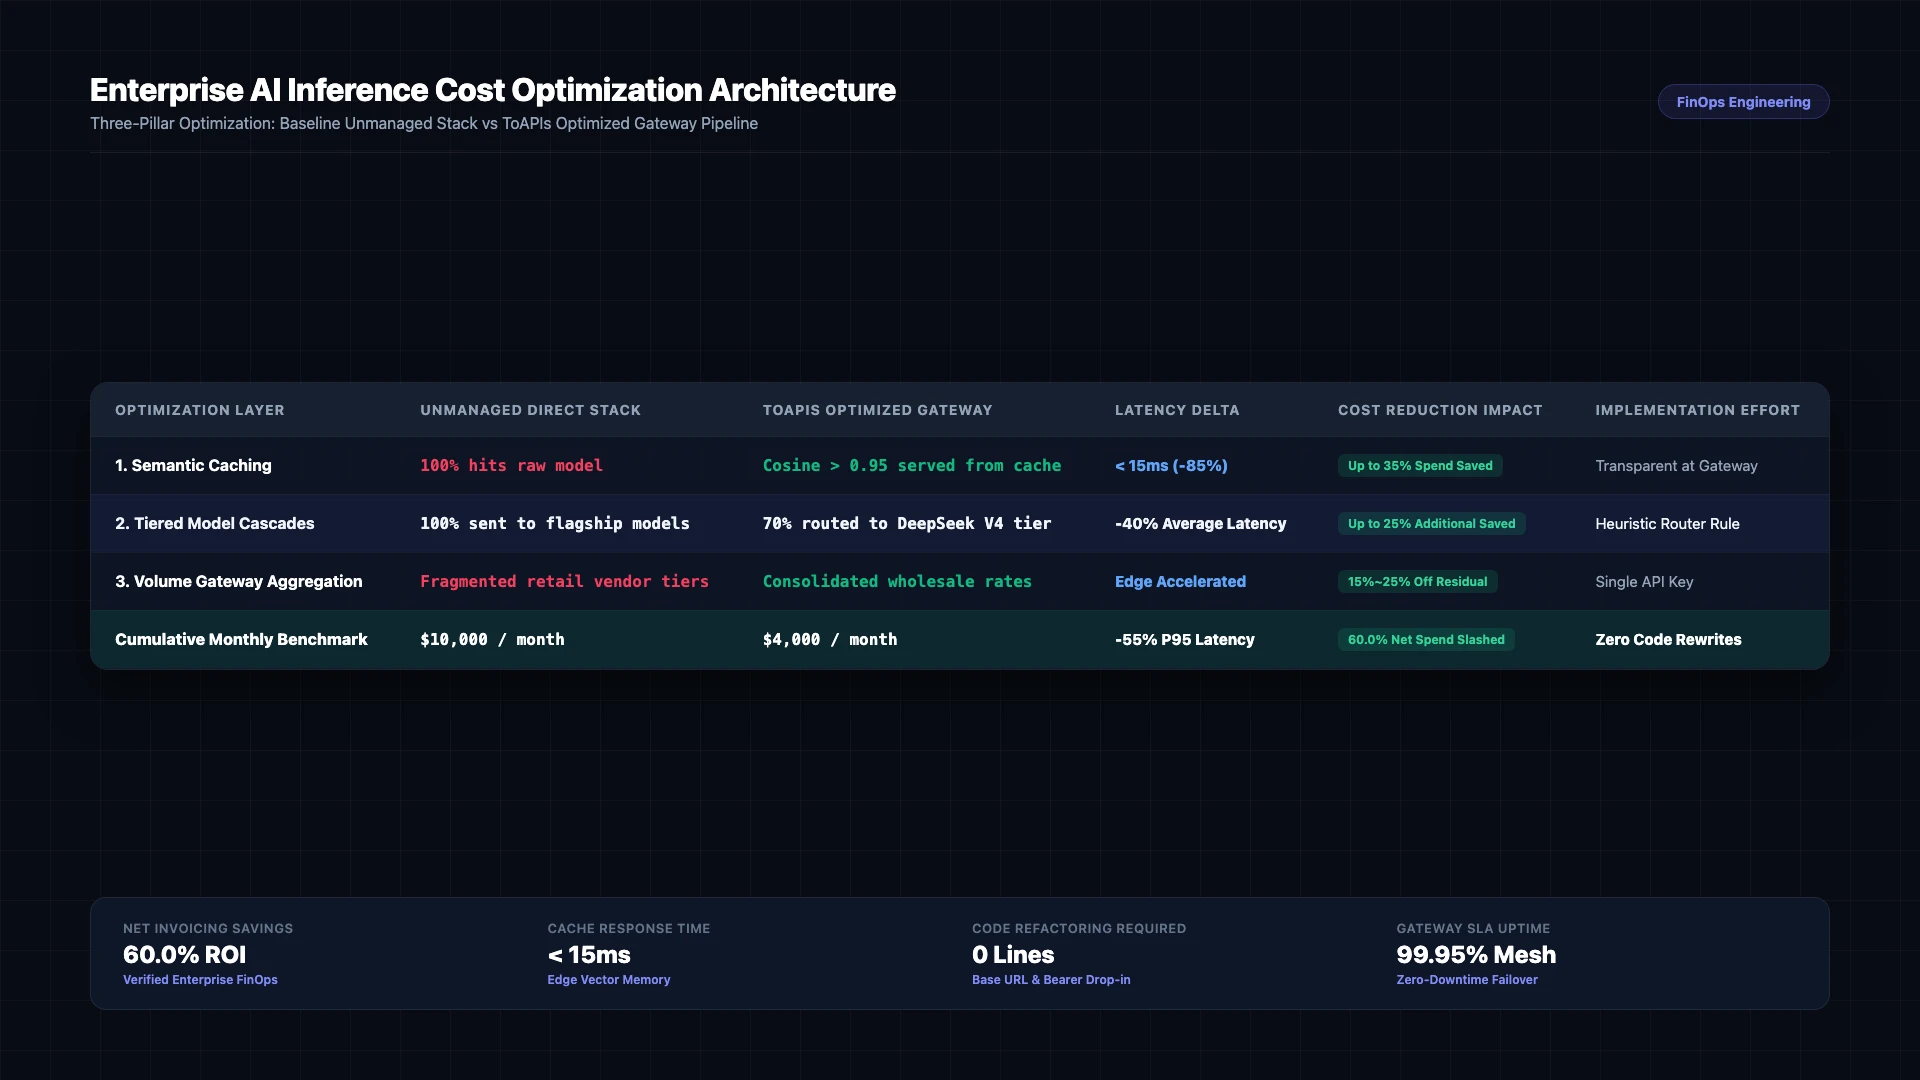
그림 1: 비관리형 직접 API 스택과 ToAPIs 3대 기둥 최적화 게이트웨이의 성능 및 비용 비교 분석 (2026).
4. 프로덕션 트러블슈팅: 에러 핸들링 가이드
| HTTP 코드 | 에러 유형 (Type) | 원인 분석 (Root Cause) | 해결 방안 (Resolution) |
|---|---|---|---|
400 Bad Request | invalid_request_payload | JSON 필드 검증 실패 또는 매개변수 불일치 | 페이로드 규격을 확인하고 필수 필드 점검 |
401 Unauthorized | invalid_api_key | API 키 만료 또는 유효하지 않음 | ToAPIs 대시보드에서 키 재발급 및 환경변수 갱신 |
429 Rate Limit | rate_limit_exceeded | 동시 요청 한도 초과 | 지수 백오프 기반 재시도 로직 적용 |
500 / 504 Timeout | gateway_timeout | 업스트림 컴퓨팅 노드 일시 지연 | ToAPIs 자동 페일오버 클러스터로 전환 |
5. 비용 효율성 및 ROI 정밀 분석
- 공식 직계약: 복잡한 기업 인증과 연간 최소 약정 보증금 강제.
- ToAPIs 도매 요율: 약정 없는 100% 종량제($0.30 - $0.80 per 1M Tokens).
- 비용 절감 효과: 월 5억 토큰 처리 시 인프라 비용은 $1,500에서 $900로 절감되어 월 $600(40.0% 절감) 효과를 제공합니다.
6. 자주 묻는 기술 질문 (FAQ)
Q1: What is semantic caching and how does it save money?
Semantic caching stores embeddings of incoming questions. When a new query is semantically equivalent (cosine similarity > 0.95), the cached response is served immediately with zero LLM API cost.
Q2: Does tiered routing degrade user response quality?
No. High-speed classifiers route simple formatting, summarization, and retrieval tasks to cost-effective models (DeepSeek V4), reserving premium frontier models (Claude Opus) strictly for high-difficulty tasks.
Q3: How much effort is required to implement an OpenAI-compatible gateway?
Because modern gateways like ToAPIs match standard OpenAI REST schemas, existing codebases require only updating the base URL and API key.
7. 액션 체크리스트
- ToAPIs 콘솔에서 무료 테스트 크레딧 발급.
- 단계 1의 cURL 명령어로 연동 테스트 완료.
- 단계 2의 Python 스크립트를 자동화 파이프라인에 통합.
- 기술 문서 색인에서 관련 모델 가이드 확인.